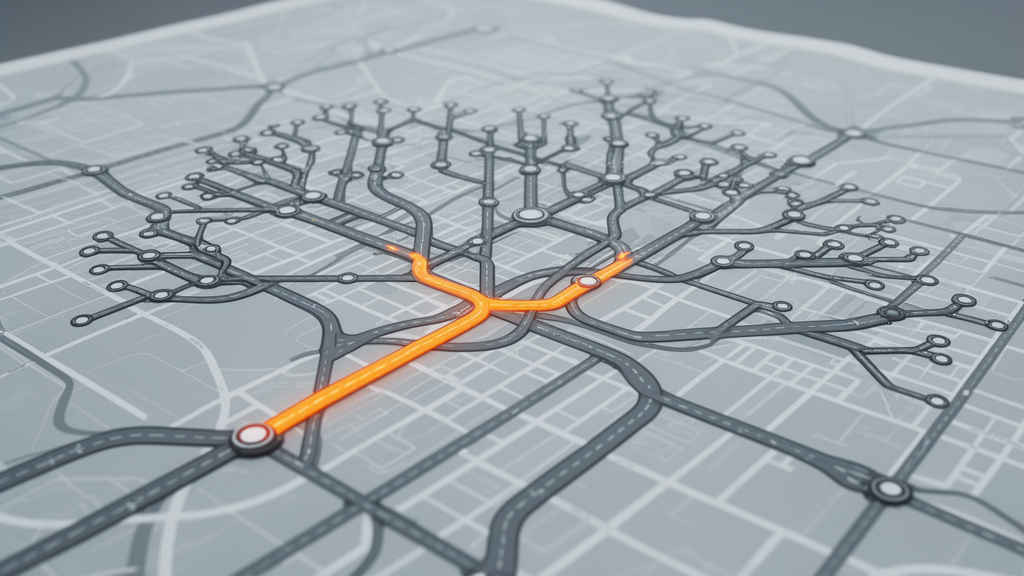
A research team led by computer scientists Yishu Wang, Jinlong Chu, Ye Yuan, Yongjiao Sun, Xiangguo Zhao, and Hangxu Ji has developed an algorithmic framework that substantially accelerates shortest path computations across large, dynamic networks under complex operational rules. Published in Data Science and Engineering, the study introduces a label-partitioned tree decomposition model called LP-Tree and a complementary Parameter-Separated two-hop indexing scheme designed for the Time-Dependent Label-Constrained Shortest Path, or TD-LCSP, problem. By decoupling label sequences from time-dependent travel time functions and restructuring network graph hierarchies, the framework achieves sub-millisecond to low-millisecond query latencies on large road networks while cutting index storage footprints by more than half compared to existing baseline methods. Across experimental evaluations on five real-world continental and metropolitan road networks containing up to nearly two million vertices, the proposed method delivered query processing speedups ranging from 45.2 percent to 63.8 percent over extended state-of-the-art baselines.
Point-to-point shortest path computation represents one of the most fundamental operational primitives in network analysis, underpinning applications spanning urban navigation, multi-modal trip planning, chemical manufacturing, and logistics routing. While classic shortest path formulations assume static edge costs and unconstrained traversals, practical deployment scenarios routinely enforce semantic or operational restrictions where only paths traversing specific sequences of edge types are valid. To reflect these requirements, earlier investigations formulated label-constrained shortest path models, which assign categorical labels to graph edges and enforce formal language constraints over valid route sequences. However, as the authors observe, prior research predominantly addressed the mere existence of labels along routes on static topologies with unchanging edge weights. In real-world operational environments, two critical dynamics intersect: edge traversal durations fluctuate continuously over time, and edge labels must often appear in strict sequential order rather than arbitrary subsets to maintain physical or semantic feasibility.
To illustrate the necessity of joint temporal and sequential constraints, the researchers highlighted three concrete engineering domains where static and unordered formulations fail. In multi-modal urban transit systems, commuters navigate journeys combining walking, bus routes, subway lines, and shared bicycles, where physical connections require strict sequential transitions and edge traversal times vary sharply between rush hours and off-peak periods. In pharmaceutical synthesis pipelines, automated reaction networks model chemical transformation stages as labeled edges where synthesis procedures must strictly execute in predefined procedural orders, while chemical reaction efficiencies shift dynamically due to catalyst degradation, reagent sensitivity, and automated instrument scheduling. Similarly, in international supply chain logistics, goods transition across discrete operations including marine shipping, customs clearance, and overland freight, where border inspection procedures and port congestion introduce time-dependent transit costs that alter the optimality and feasibility of end-to-end transportation paths depending on the exact arrival hour at each logistical hub.
Addressing these combined constraints requires solving the Time-Dependent Label-Constrained Shortest Path problem, an optimization problem that the authors formally proved to be computationally intractable. Their complexity analysis demonstrates that TD-LCSP is NP-hard in the general setting via two distinct polynomial-time reductions. First, the classical label-constrained shortest path problem subject to context-free language constraints reduces to TD-LCSP when assigning constant travel time functions across all edges, which corresponds to setting each function to a single turning point. Second, the time-dependent shortest path problem under non-monotonic travel time functions reduces to TD-LCSP under a trivial regular language constraint that permits every possible label permutation. Beyond theoretical hardness, real-world implementations face steep practical challenges: evaluating vast collections of asymmetric piecewise linear travel time functions consumes immense storage space, while simultaneously validating time-dependent arrival windows and non-deterministic finite automaton state transitions along extended paths rapidly exhausts computing memory.
To overcome these computational bottlenecks, the authors devised the LP-Tree decomposition framework, which expands classical graph tree decomposition through an integrated three-phase vertex elimination strategy. Standard tree decomposition methods, such as the traditional minimum degree elimination heuristic, select vertices solely based on topological degrees to limit decomposition treewidth, completely ignoring label distributions and temporal profile structures. This structural blindness results in fragmented label groupings and forces graph algorithms to navigate massive combinatorial search spaces, generating an excessive number of invalid path explorations during query traversals. In contrast, the LP-Tree construction coordinates three deliberate selection stages: the first phase preserves the minimum-degree-first prioritization framework to ensure fundamental treewidth bounds, while the second phase acts as a targeted tiebreaker by selecting vertices exhibiting the highest label similarity, defined as the ratio of the most frequent incident edge label to the vertex’s total incident label count.
By prioritizing high label similarity during intermediate decomposition steps, the LP-Tree algorithm deliberately positions tree nodes with fewer label partitions toward the leaf layers of the resulting hierarchical tree decomposition. When candidate vertices share identical degrees and matching label similarity values, the third phase selects vertices whose travel time functions feature the fewest turning points, thereby substantially boosting computational efficiency during the composition of travel time functions in graph reduction operations. The authors integrated a non-deterministic finite automaton into this decomposition procedure to validate regular language path constraints directly during graph reductions. Under their reduction operator, when an intermediate vertex is removed from the active graph, pairwise directed connections between its incident neighbors are evaluated through sequential automaton state transitions. Valid compound connections receive composite piecewise linear travel time functions derived from sequential function composition, mathematically preserving the non-decreasing FIFO property of underlying road networks while systematically eliminating label-incompatible transitions before indexing begins.
While the LP-Tree decomposition provides an innovative structured representation that accelerates localized and intermediate path computations, evaluating long-distance queries between distant nodes across root-level lowest common ancestors can still encounter computational bottlenecks due to recursive function composition. To resolve this limitation without inflating storage requirements, the team designed the Parameter-Separated two-hop indexing scheme. Traditional two-hop indices precompute shortest path profiles between network vertices and designated intermediate hub nodes, but storing full time-dependent functions for every vertex-hub pair leads to severe memory inflation because empirical traffic functions feature asymmetric turn points across different routes. The Parameter-Separated index resolves this fundamental inefficiency by decoupling label paths from numerical travel time parameters, storing unique departure-time and travel-time coordinate pairs within a centralized global parameter pool and referencing them through compact pointer sequences rather than duplicating identical temporal curves across multiple routing bags.
Under this decoupled storage architecture, each network vertex maintains incoming and outgoing label sets containing structured tuples that record hub node identifiers, pointers referencing specific turn-point coordinate sequences in the parameter pool, automaton state transition outcomes, and next-hop or previous-hop direction identifiers. The authors established theoretical storage efficiency bounds for this parameter-sharing mechanism, demonstrating that even in worst-case scenarios where turn points cannot be shared across edges, the index remains strictly more compact than traditional two-hop indices due to the pointer-based deduplication structure. During query execution, the framework applies a three-step processing pipeline: it first identifies candidate hubs at the lowest common ancestor bag that satisfy automaton state requirements, executes a temporal multi-way join between outgoing and incoming travel time functions to confirm arrival compatibility, and finally evaluates optimal travel costs before reconstructing the complete concrete path while maintaining dual visited-node sets to prevent cyclical loops.
The researchers conducted comprehensive empirical evaluations using an experimental implementation written in standard C++ and compiled with aggressive compiler optimizations on an Ubuntu Linux server equipped with an Intel Xeon Silver 4214 processor and 128 gigabytes of memory. Their benchmarks examined five publicly available, real-world road networks from the Stanford Network Analysis Project repository, representing San Francisco, New York City, Colorado, Florida, and California, spanning from 262,104 vertices in New York City to 1,971,278 vertices in California. Each network modeled travel time profiles as piecewise linear functions over an 86,400-second daily domain, varying turn-point counts from two to six around a default baseline of three daily traffic phases, and evaluated synthetic categorical edge labels ranging from three to seven functional classifications across 10,000 query pairs per network. Comparative baselines were established by extending the state-of-the-art PCSP label-constrained index with dynamic temporal capabilities and adapting the TD-APPO time-dependent index to enforce regular label restrictions.
Experimental results across all five road networks demonstrated that the Parameter-Separated indexing architecture delivered dramatic reductions in storage overhead and significant query latency improvements over both baseline systems. Furthermore, the authors observed that because the parameter pool isolates numerical travel times from structural label transitions, updates to automaton operational rules require refreshing only local hub label entries without recomputing or rebuilding global time profiles, establishing a scalable and resilient algorithmic foundation for dynamic routing in modern transportation networks.
Subject of Research: Label-constrained shortest path computation on time-dependent graphs
Article Title: Efficient Label-Constrained Path Queries on Time-Dependent Graphs via LP-Tree Decomposition
Article References: Wang, Y., Chu, J., Yuan, Y., Sun, Y., Zhao, X., & Ji, H. (2026). Efficient Label-Constrained Path Queries on Time-Dependent Graphs via LP-Tree Decomposition. Data Science and Engineering, 11(3), 616-635. https://doi.org/10.1007/s41019-026-00345-x
Image Credits: AI Generated
DOI: 10.1007/s41019-026-00345-x
Keywords: graph algorithms, shortest path queries, time-dependent networks, label constraints, tree decomposition, parameter separation, road networks, computational complexity, Efficient, Label-Constrained, Path, Queries
News Source: Denise Maddox. (November 8, 2026). LP-Tree Decomposition Accelerates Label-Constrained Routing on Dynamic Road Networks. Scienmag.