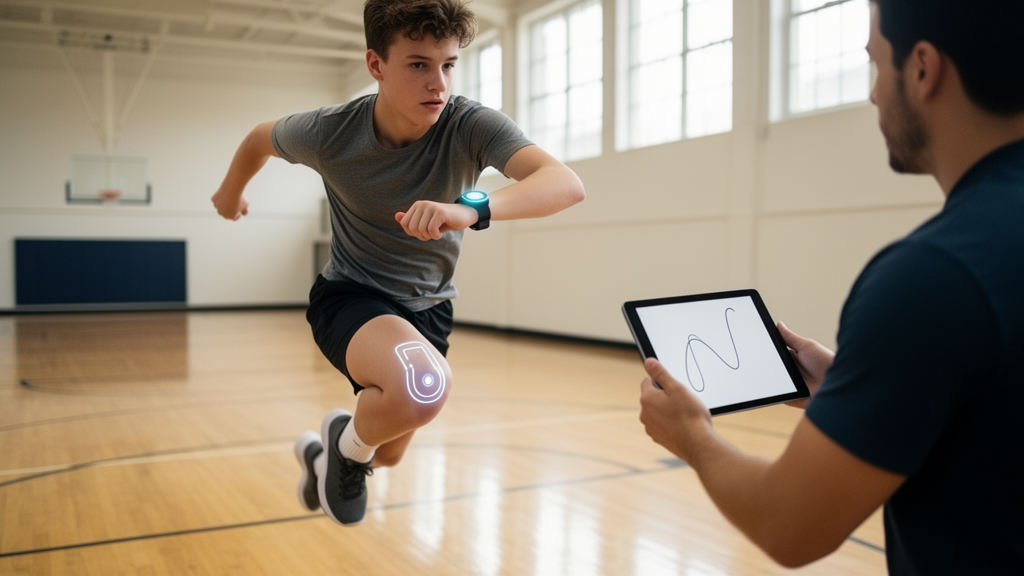
Physical education classes have long depended on the trained eye of an instructor to spot a flawed jump, an unstable landing, or a fatigued stride. A study published in Discover Artificial Intelligence proposes a computational alternative: a system that reads streams of data from accelerometers, gyroscopes, heart-rate monitors, and electromyography sensors worn by students, and then decides in milliseconds how their movement should be corrected and how likely they are to be hurt if nothing changes. The researchers, led by Jie Li, built a model they call FO-OC-HRL, short for Fossa Optimizer-tuned Option-Critic Hierarchical Reinforcement Learning.
The name is a mouthful, but the architecture is conceptually elegant. Reinforcement learning systems learn by trial and reward, and hierarchical versions split the decision-making into layers. In this design, a high-level policy chooses among broad motor skill correction strategies, while low-level option policies translate those strategies into concrete corrective actions and exercise recommendations tailored to the individual learner's current movement state.
The Option-Critic architecture is central to why this works without hand-crafted sub-goals. Each option is formally defined as a triplet: an initiation set specifying the learner states in which the option can activate, a stochastic termination function determining when the option should end, and an intra-option policy mapping states to corrective actions. The system learns the policy over options, the intra-option policies, and the termination conditions simultaneously, end to end.
High-level and low-level value networks are updated with separate target computations, and the option-value network is trained by minimizing a mean squared error loss between predicted and target option values. Layered on top is the Fossa Optimizer, a nature-inspired metaheuristic modeled on the cooperative hunting behavior of the Malagasy fossa, Cryptoprocta ferox. Its job is to tune the hyperparameters of the reinforcement learning architecture automatically rather than leaving them to manual guesswork.
The optimizer maintains a population of candidate hyperparameter configurations, evaluates each by the average episodic reward achieved during policy learning, and refines the population through two phases: an exploration phase simulating the fossa assaulting and proceeding toward a lemur, and an exploitation phase simulating the chase to catch it. Configurations survive only if they improve the fitness value, which converts reward maximization into a minimization objective. The raw material for all this learning came from an open-source Wearable Motor Skill Assessment dataset containing 7,000 student records with 30 attributes.
Twenty-eight input features capture sensor measurements, movement performance, physiological responses, training characteristics, and biomechanical indicators, while two target variables record motor skill status and injury risk level. The signals were first denoised with a Butterworth filter, which suppresses high-frequency noise and motion artifacts while preserving essential movement information, then standardized with Z-score normalization so every feature has zero mean and unit variance. Feature extraction followed, using the Discrete Wavelet Transform.
This time-frequency method decomposes each preprocessed signal into approximation coefficients from a low-pass filter and detail coefficients from a high-pass filter, producing discriminative representations of movement quality, muscle activation, and biomechanical characteristics. The resulting feature vectors feed the hierarchical learner, which must map a student's momentary state to both a correction strategy and an injury risk judgment. The performance numbers are striking, though they come with important caveats.
On a held-out test set of 1,400 records, the FO-OC-HRL model achieved 98.27 percent accuracy, 98.11 percent precision, 97.96 percent recall, an F1-score of 98.03 percent, and a Matthews correlation coefficient of 0.972. Training took 39.58 seconds, inference 12.84 milliseconds per sample, decision-making 7.86 milliseconds, and memory usage 2.04 gigabytes, all on a consumer NVIDIA GeForce RTX 3060 GPU running Python 3.11 with PyTorch and Stable-Baselines3 libraries. An ablation study reveals where the gains come from.
The Option-Critic model without wavelet features reached 94.62 percent accuracy; adding DWT feature extraction lifted it to 96.84 percent; and the Fossa Optimizer's hyperparameter tuning pushed it to the final 98.27 percent. In motor skill correction terms, the model reported 97.76 percent movement accuracy, 97.38 percent posture stability, and a 97.42 percent correction rate, with an episode success rate of 97.36 percent after converging within 552 episodes at an average reward of 968. Compared against earlier approaches retrained on the same data under identical conditions, the new model outperformed a BPNN-based sports action identifier, an Earthworm Optimized Graph Neural Network for injury prediction that had reached 96 percent accuracy, and a Deep Ensemble Optimized Transformer-Reinforcement Learning method.
The authors attribute this to the hierarchical decision structure, which existing classification-only systems lack: those models can label a movement as flawed but cannot generate an adaptive corrective action that changes as the learner's fatigue, biomechanics, and skill evolve. The authors are candid about the limits. The model was evaluated on a single dataset under controlled conditions, and the study did not directly measure whether anyone actually avoided an injury.
The reported metrics reflect classification and correction performance, not confirmed injury reduction. Whether model-guided corrective feedback can lower injury incidence in real gyms and playing fields will require the prospective, multi-student, multi-sport validation the researchers outline as future work. Until then, the fossa's hunting strategy remains a promising simulation of a coach's instinct, not yet a proven substitute for one.
Subject of Research: A wearable sensor-guided hierarchical reinforcement learning model for adaptive motor skill correction and injury-risk assessment in physical education
Article Title: Wearable sensor-guided hierarchical reinforcement learning for adaptive motor skill correction and injury-risk assessment in physical education
Article References: Li, J. (2026). Wearable sensor-guided hierarchical reinforcement learning for adaptive motor skill correction and injury-risk assessment in physical education. Discover Artificial Intelligence, 6(1), Article 1590. https://doi.org/10.1007/s44163-026-02535-y
Image Credits: AI Generated
DOI: 10.1007/s44163-026-02535-y
Keywords: wearable sensors, hierarchical reinforcement learning, Option-Critic, Fossa Optimizer, motor skill correction, injury risk, physical education, electromyography, discrete wavelet transform, machine learning, hyperparameter tuning, biomechanics
News Source: Courtney Benton. (October 27, 2026). Research report: Wearable sensor-guided hierarchical reinforcement learning for adaptive motor skill correction and injury-risk assessment in physical education. Scienmag.